How Pulse Local works
A small model.
A careful harness.
Pulse Local is a budgeting app that answers questions about your money with a 0.6B model running on your machine.
The model is small on purpose. What makes it reliable is everything built around it.
0.6B
parameters in the model, running on your machine
4 in 5
questions answered by code, before the model sees them
76 vs 75
real questions answered well, Pulse Local against GPT-4.1-mini, out of 77
2
kinds of network request, ever: the setup download and an optional update check
Why privacy is the product
Your transactions are your life, itemised.
Where you live, who you pay, what keeps you up at night. Most budgeting apps keep that on their servers. The ones that keep it on your disk still send your question, and the rows that answer it, to a hosted model.
A promise not to train on it is a policy, not an architecture. So we made the architecture the promise: the model is a file next to your ledger, and there is nowhere to send it.
The gap
“Local” usually means your data. Not your question.
Yourledger
Yourquestion
Hostedbudgeting apps
On theirservers
To theirservers
“Local-first”apps
On yourdisk
To a hostedmodel
PulseLocal
On yourmachine
On yourmachine
The harness
Code first. The model last.
A 0.6B model is fast, private and unreliable at arithmetic. So a question walks past exact tools first, and the model only sees what nothing else could answer: about one question in five.
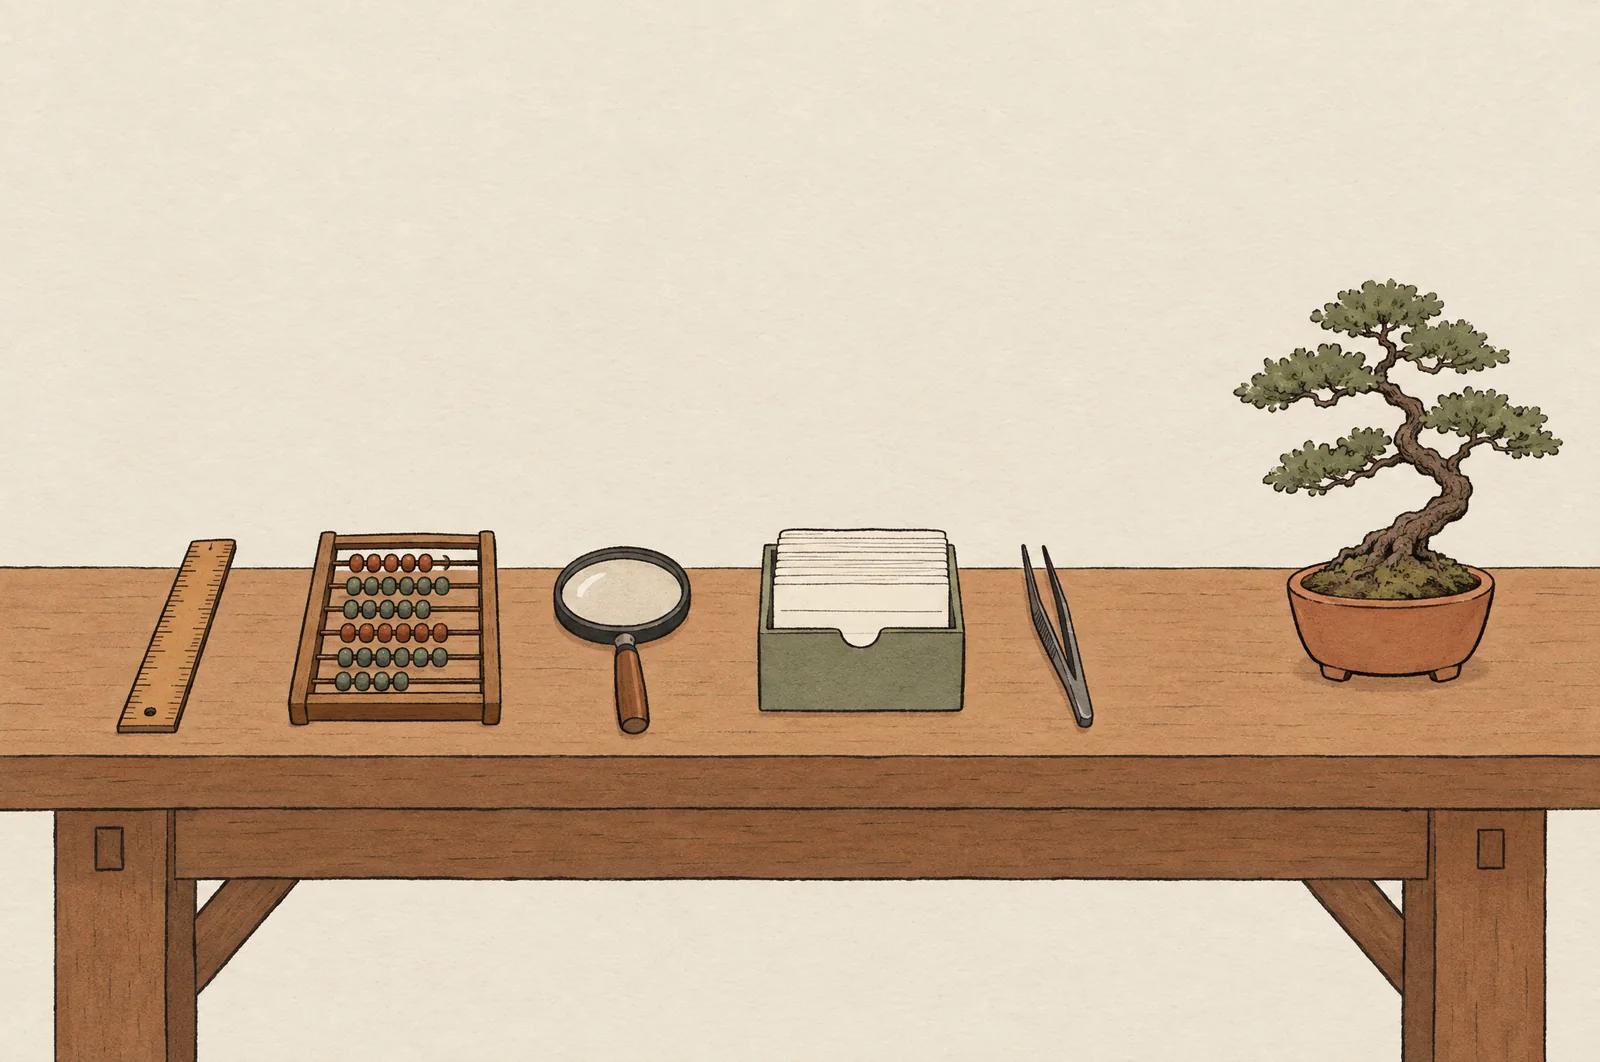
- 01ArithmeticExact maths, only when every number in the question is unambiguous. Shows its working.code
- 02Ledger factsCounts, date ranges and accounts, read straight from your file.code
- 03The no-internet ruleAnything live, like today’s rates, is declined out loud, never guessed.code
- 04RouterA 37 MB embedding model picks the 1 to 3 tools worth offering, in about 6 ms.embedding
- 05Merchant tableReads card-statement prefixes and searches your own ledger for the rest.code
- 06Query plannerReads six parts of a question: what, where, when, grouping, comparison, aggregate. 29,160 query shapes enumerated, none broken.code
- 07Written knowledge373 reviewed answers for concepts, and 37 notes for “should I” questions that lay out the trade-off and leave the call to you.code
- 08The modelQwen3-0.6B, fine-tuned with LoRA, 397 MB. Gets 1 to 3 tools and only the questions nothing above could answer.model
Every answer then passes a format check and a posture guard: Pulse describes your money, it never tells you what to do with it.
What we learned
The model was never the bottleneck.
The same 0.6B model scores 55 on its own and 98 inside the harness. A model seven times larger, without it, scores 81. We tried the obvious levers on the weights. They barely moved.
Held-out averages, higher is better. The lesson we build on: spend the effort on code coverage and written knowledge, not on the weights.
The numbers
Level with a hosted model, on the questions people ask.
77 real budgeting questions, on a real ledger
answered well
48-question benchmark
score out of 100
Held-out sets we had never seen
average of four, out of 100
We publish the set we lose: on questions we had never seen, the hosted model is 1.7 points ahead. Zero directive answers on every set. Zero confidently wrong reads across 48 intent checks, typos included. Code answers in about 40 ms; the model starts in 95 ms and writes about 120 tokens a second.
The product
A complete budgeting app, not a demo.
- Everything a budget needs. Plans, rules, splits, cash flow, a forecast, and a chat that answers from your own figures.
- Exact to the cent. Every total is calculated by code, never guessed by the model.
- Open weights. The model is on Hugging Face under Apache 2.0, so anyone can read what runs before they run it.
- Free, or pay what you want. Optional bank sync (US) comes with a yearly Sync Pass: our server holds the connection token and nothing else; transactions pass through and are never stored.
Why now
Small open models became good enough to steer. A harness makes them reliable. That turns privacy from a sacrifice into the default.
We believe AI for money should be local by default: the model runs where your data lives, on open weights anyone can read.
What is next
- Windows, after the Mac.
- Bank sync beyond the US.
- The questions the model still gets wrong, one written answer at a time.
The private layer for personal finance.